What it cannot read, it names in every answer
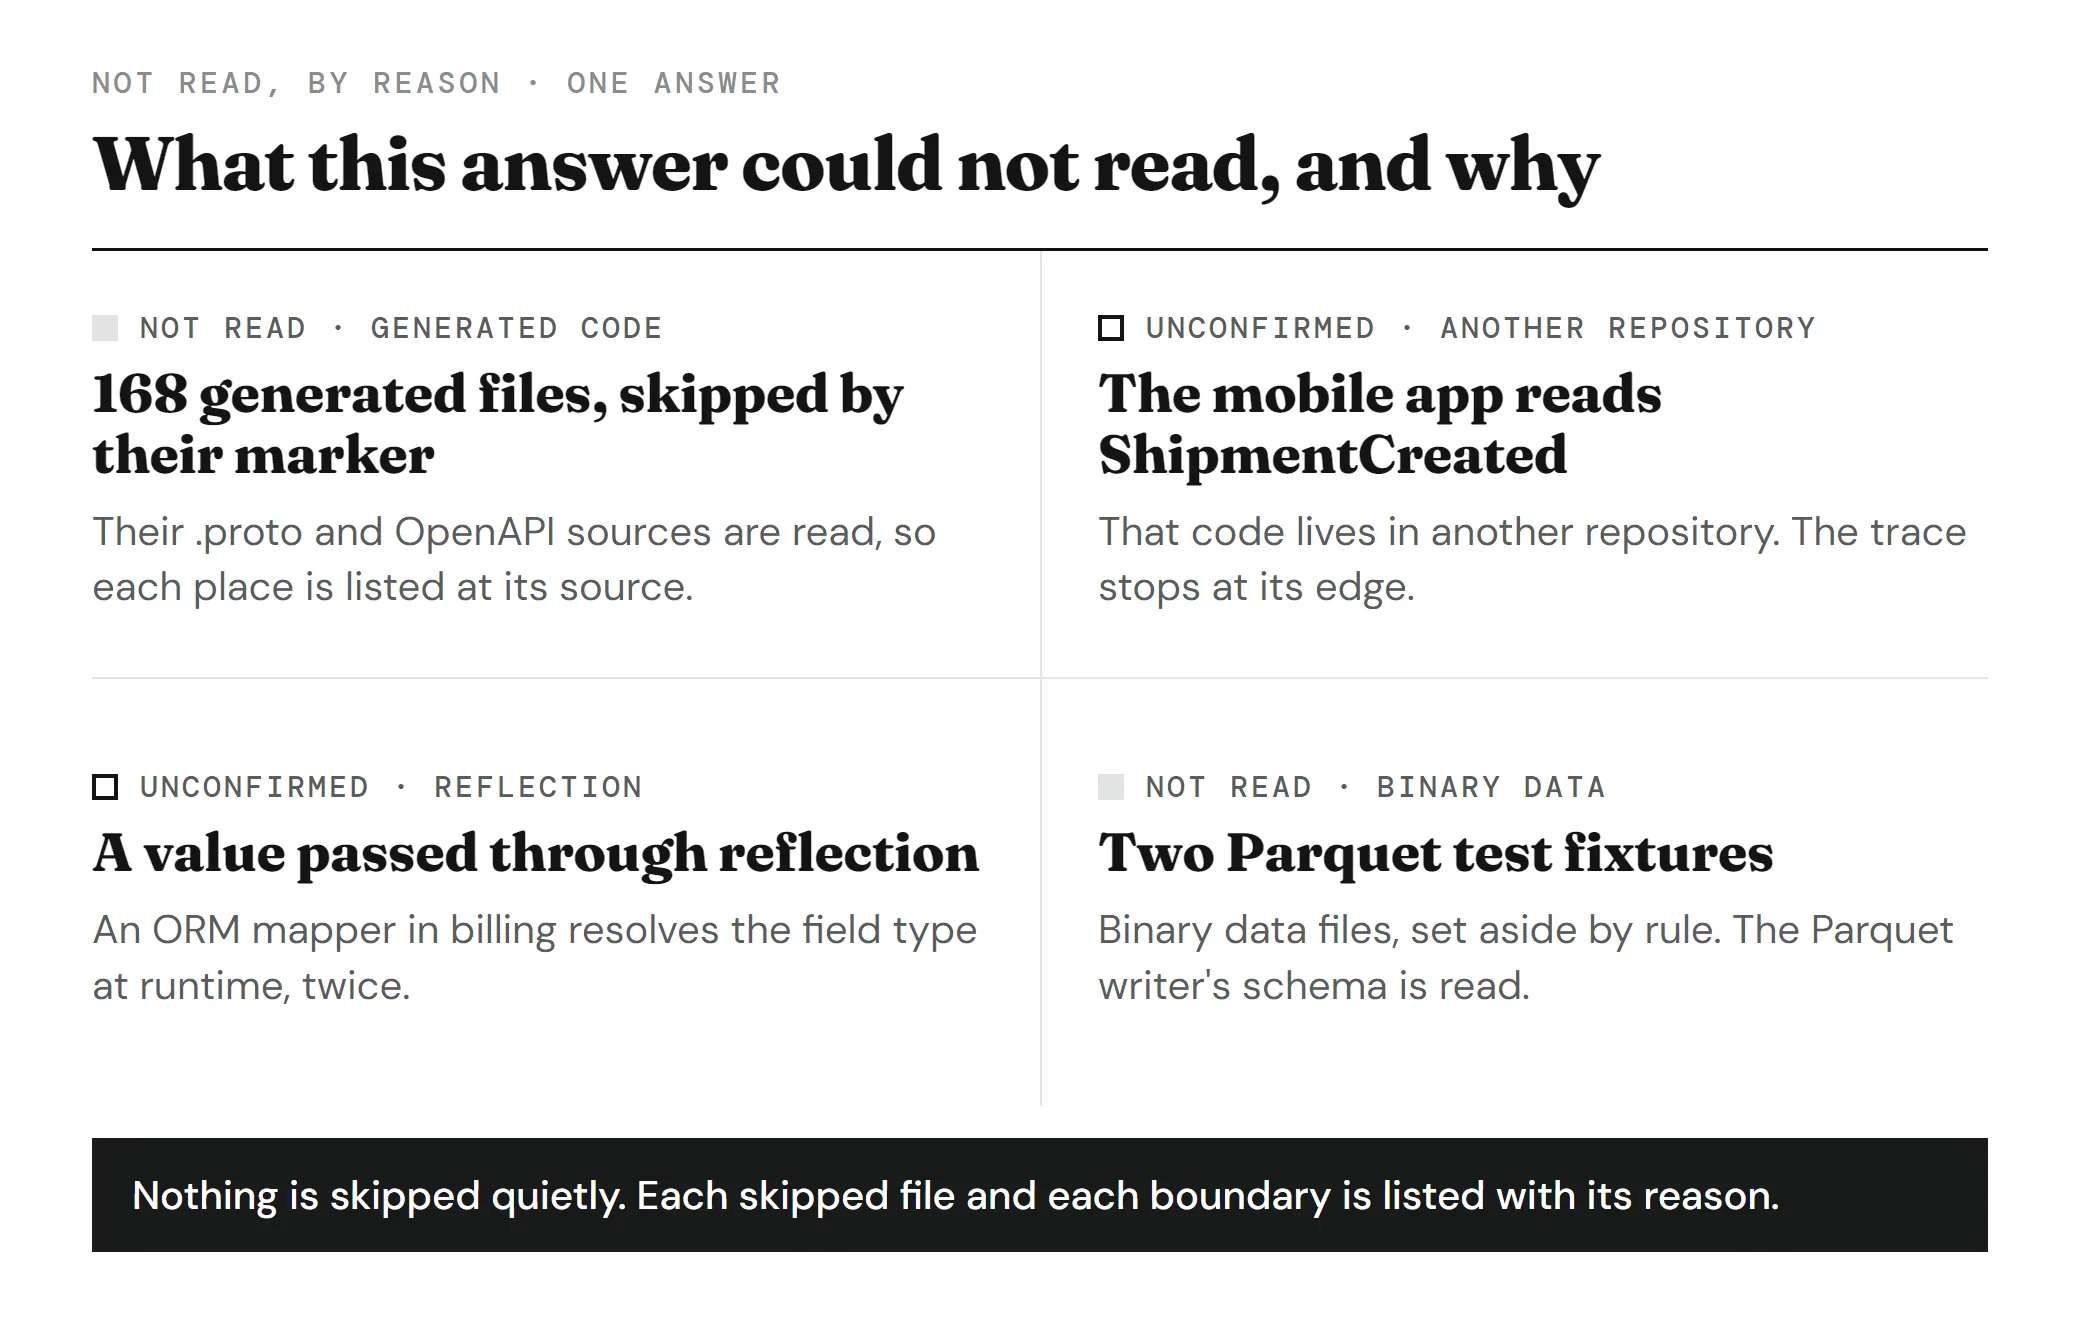
Nothing is skipped quietly. Each file set aside and each boundary reached is listed with its reason.
Over 60 million tokens, about six million lines, a snapshot is refused rather than sliced. Exclude directories, and every answer names them.
- Generated code
- skipped by marker; its .proto or OpenAPI source is read
- Another repository
- a trace that reaches one stops there, unconfirmed
- Runtime reflection
- and deploy-time configuration: unconfirmed, boundary named
- Binaries, data files over 1 MB
- set aside; schemas always read
At about 100,000 lines or fewer, you do not need us
100,000
lines, under which one 1M-token window holds it
A 1M-token window takes the whole repository, for about $10 of input a question.
Nor does a single-language codebase where widening the type and compiling finds every place for free.
Nor a team that wants the change made, or a company whose code may not leave its own machines, even for minutes.
Where the code goes for one question, and the minute it is gone
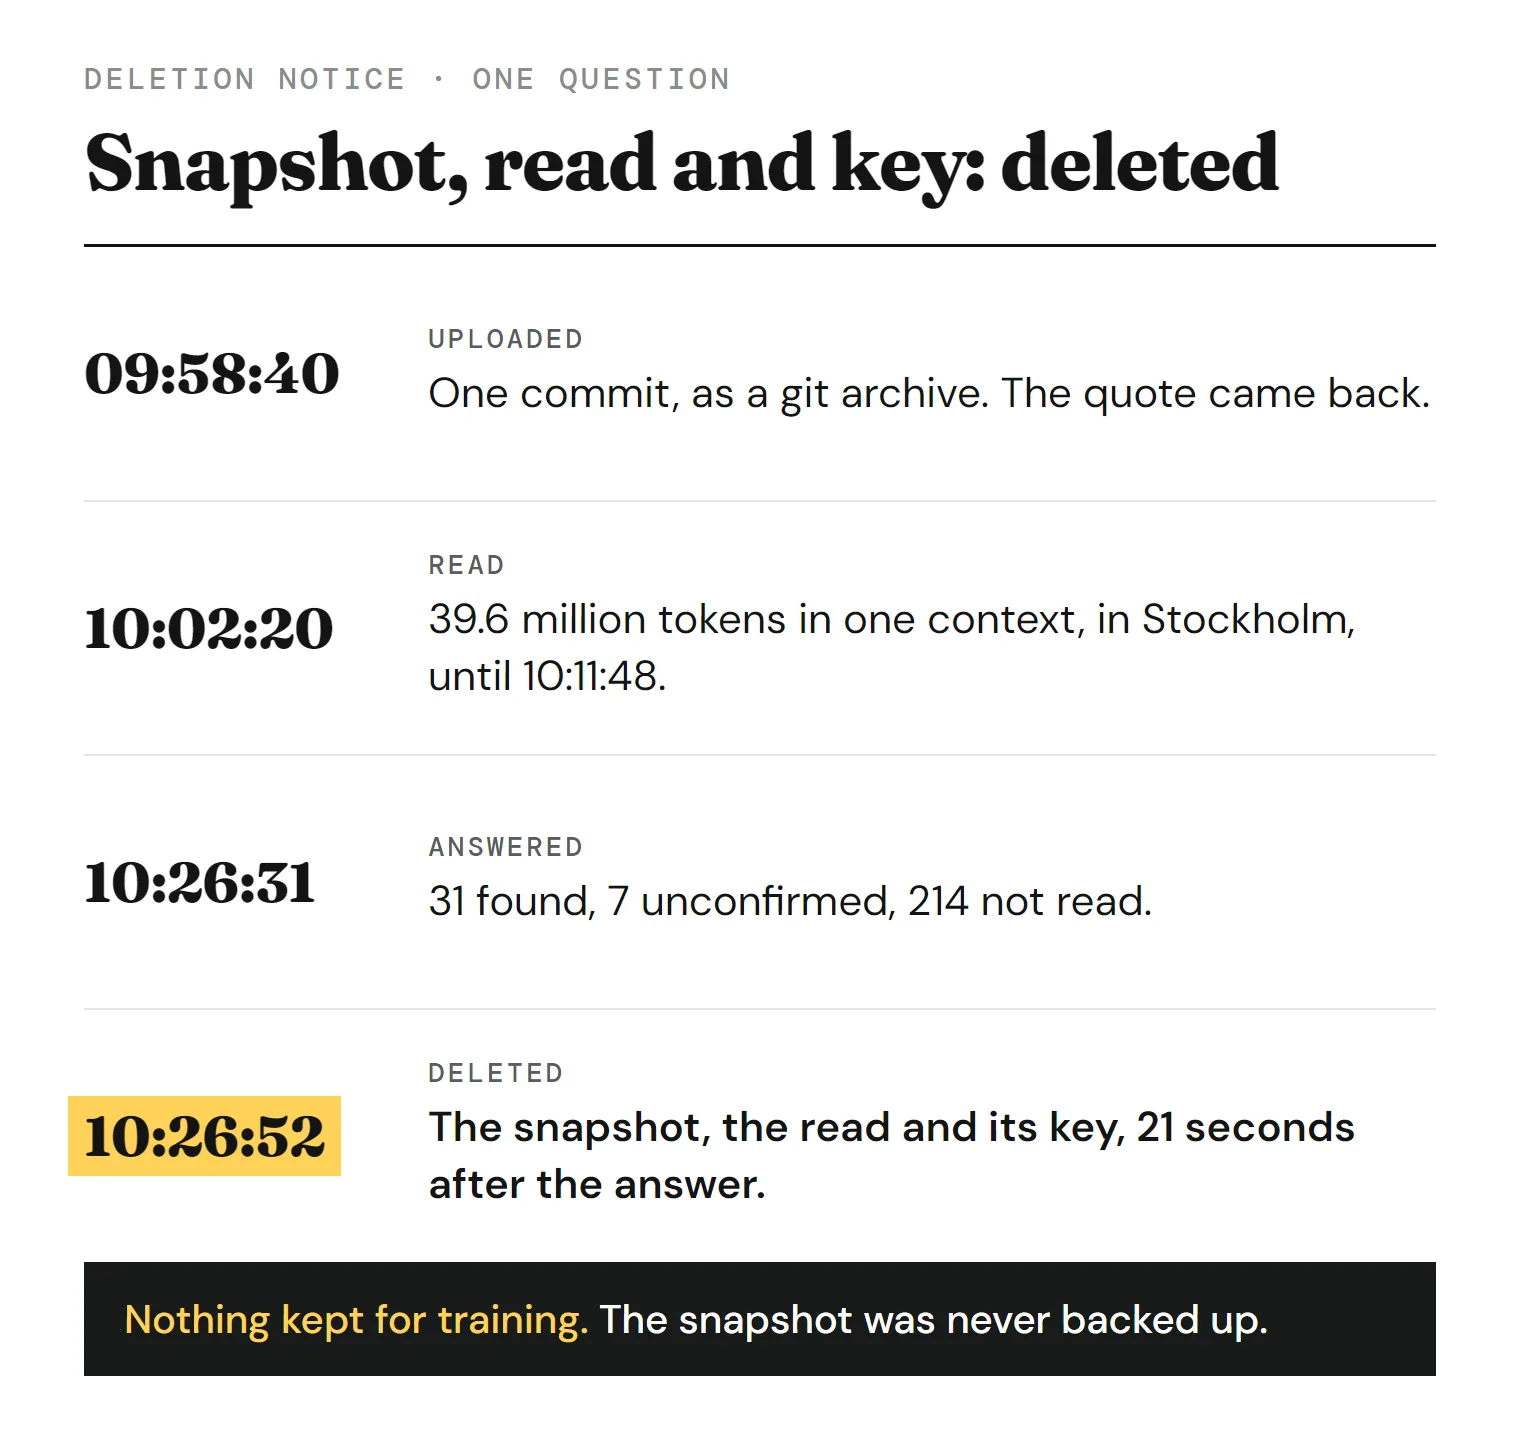
One commit arrives as a git archive, the route from Azure Repos or any other host, or through a read-only GitHub or GitLab token used once. Neither a SOC 2 report nor an ISO 27001 certificate is in hand yet. In their place: a DPA under the GDPR and Danish law, the subprocessor list, and a deletion notice for every snapshot.
09:58:40
Uploaded: commit a41c9e0 of the order-id scenario, and the quote comes back
10:02:20
Read until 10:11:48: 39.6 million tokens, in Stockholm
10:26:31
Answered: 31 found, 7 unconfirmed, 214 not read
10:26:52
Deleted: snapshot, read and key, none kept for training